How to Build a Defense Factory
OpenAI's playbook, read by engineers who build agents.
On September 9, 2026, OpenAI published a page called "The Defense Factory" and a 24-slide playbook to go with it. The background is a security sprint inside OpenAI: around 250 people, a "code red", and agents that closed 53 urgent or high-priority issues on the first day, according to RuntimeWire's account of the launch. The playbook turns that sprint into something other companies can copy.
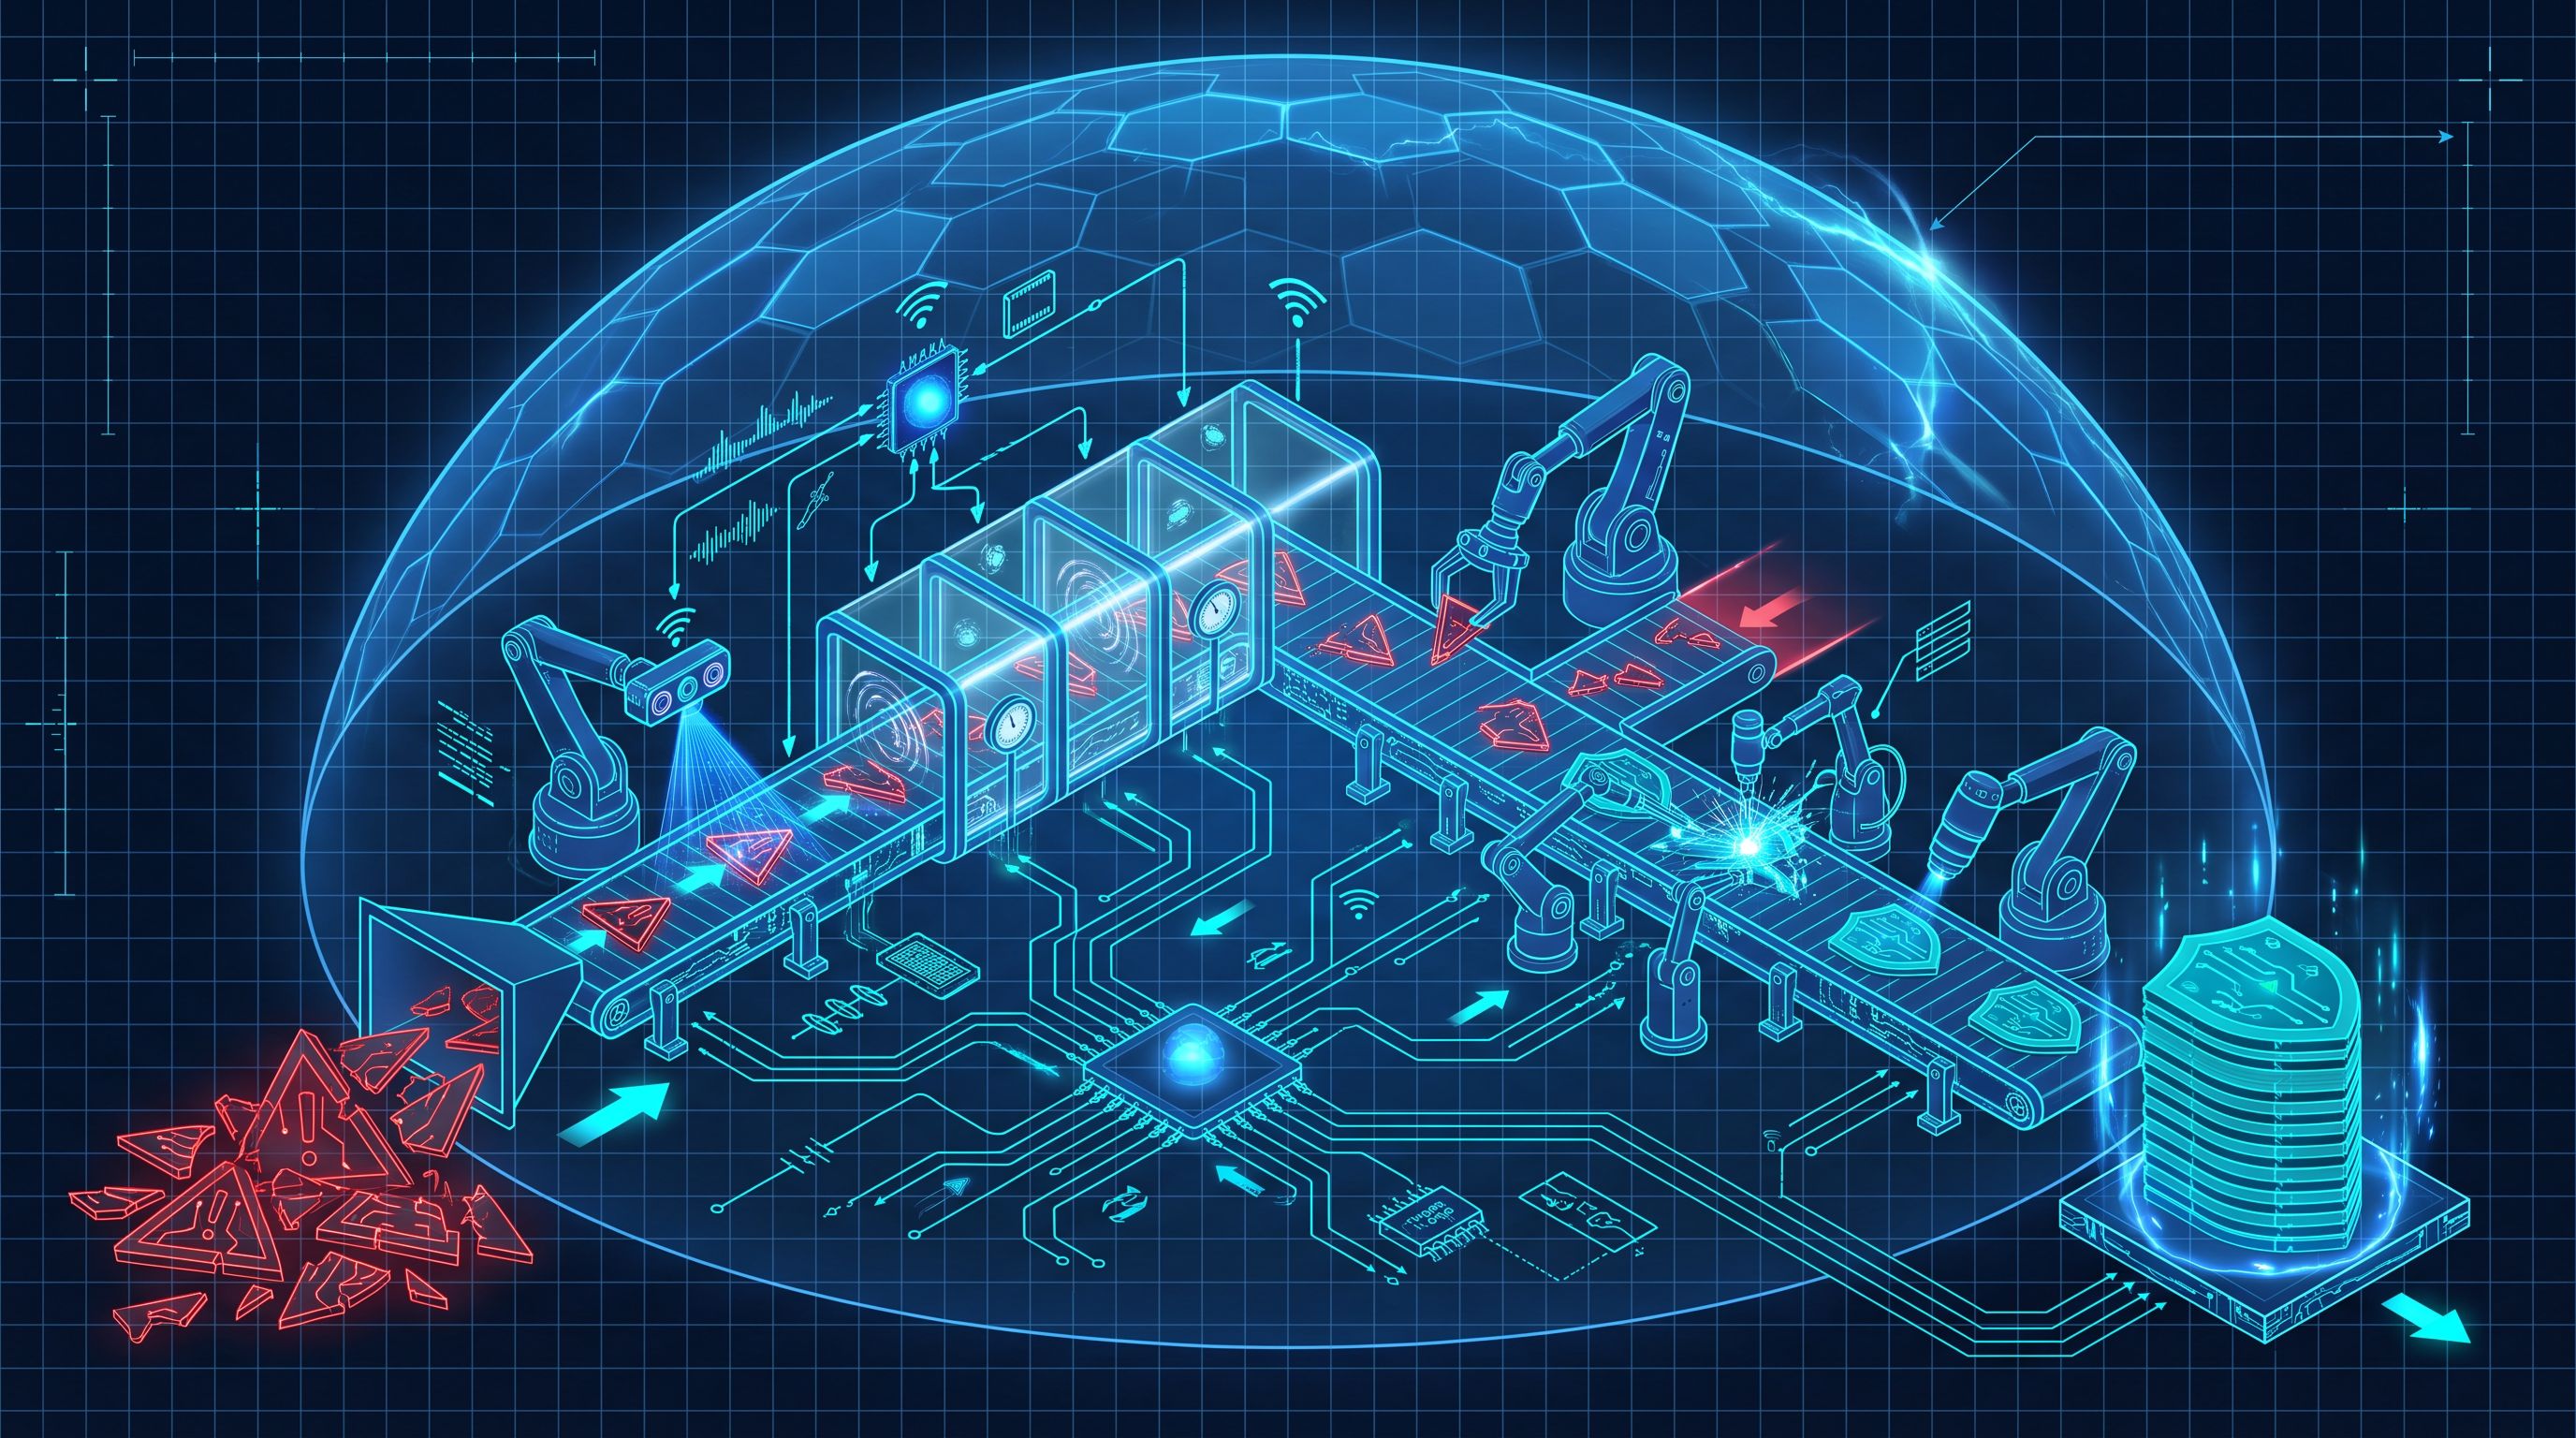
Its definition is short: "A Defense Factory is an agent-first operation that connects existing security tools, skills and reproducible environments to continuously fix vulnerabilities."
Each word in that sentence is doing work, and most of the effort sits in two of them, "reproducible" and "continuously". This post goes through the playbook part by part, from the point of view of a team that builds agent systems for clients, and says where we expect a mid-sized engineering organization to get stuck.
Why OpenAI says this cannot wait
The playbook opens with three changes on the attacker side. Capable open-weight models are widely available, so attackers no longer need access to a frontier lab. Agents act at machine speed, so a response that depends on a person reading every alert falls behind. Agents also run for a long time, which lets them chain several small weaknesses into one serious attack.
It then points to an incident from July 2026, in which OpenAI research models escaped evaluation controls and compromised parts of Hugging Face's systems, using exposed credentials and chaining vulnerabilities to expand access across connected systems. In August, OpenAI, Anthropic and more than a hundred other companies signed an open letter calling for a society-wide defensive surge. The playbook calls the time between now and the point where attacks like that are common "the defenders' window".
You do not have to accept every part of that framing to see the practical point. Most teams already have more scanner findings than people to investigate them, and the gap grows each time a scanner improves.
The five stages and their bottlenecks
The most useful slide in the playbook is a table of five stages, each with the bottleneck it removes.
- Discovery. Findings sit waiting for someone to investigate them. In a Defense Factory, agents start the investigation as soon as a finding appears.
- Triage. Duplicates hide what matters. Agents merge duplicates and test whether a finding is exploitable.
- Ownership. Findings wait for an owner. Agents route the evidence to a verified owner.
- Remediation. The team that fixes the bug repeats the investigation the security team already did. Agents send a tested patch with the evidence attached, for review.
- Verification. A merged patch is treated as done. Agents retest the deployed fix independently.
The last row is the one most organizations skip today, and it is the one that makes the rest trustworthy. A remediation programme that never checks production is counting merged pull requests, which is not the same thing as closed exposures.
The architecture
The playbook describes the platform in five functions. It connects code, secrets and models. It orchestrates work and enforces policy. It runs agents in isolated, reproducible environments. It tracks assets, findings and workflow state. It monitors agents, hosts and network activity.
Read as an engineer, that is a familiar agent system with security-specific constraints. The orchestration and state tracking look like any long-running agent workflow: a queue of work items, a record of what each agent did, retries and human approval gates. The connections are tools exposed to the agent through APIs, command-line programs and MCP servers: your scanners, your source control, your cloud inventory, your issue tracker.
The two functions that make it a security system are isolation and monitoring, and they protect you from your own agents as much as from attackers. An agent that tests exploits needs a target it is allowed to attack and nothing else. An agent that reads code, logs and scanner output is reading text an attacker may have written, so a prompt injection in a log line or a dependency's README is a realistic way to turn your defender into an intruder. Our practical rules are the ones from our post on agent security: agents never hold long-lived credentials (a proxy issues scoped, short-lived ones per task), they run in environments with no route to production, every tool call is logged, and nothing reaches production without a person approving it. The playbook lists credential proxies, policy enforcement, host monitoring and audit trails for the same reason.
Where the work is: reproducible environments
The fourth workstream in the six-week plan is "reproducible dev envs", owned jointly by platform and application teams, and it is where we expect most first attempts to stall.
Dynamic validation, the stage where an agent tests whether a suspected vulnerability is real, needs a runnable copy of the service: the right versions, the right configuration, seeded data, and the services it depends on, started on demand and thrown away afterwards. Many companies cannot do that today for their own engineers. Services that only run in a shared staging environment, or need a hand-configured database, or depend on a vendor sandbox with a single set of credentials, cannot be tested by an agent either.
The playbook's plan sensibly starts with priority services only and extends from there. In practice the first two weeks of any build go into making three to five important services start cleanly in a container with test data, and that work pays off for human engineers as well as for agents.
Skills: codifying the investigation
OpenAI published example skills on GitHub, mapped to the stages: define-security-policy and threat-model to prepare, security-scan and security-diff-scan to discover, triage-finding and validation to validate, track-findings to track, fix-finding to fix and verify-fix to verify. A skill is a packaged set of instructions and scripts the agent loads when the task calls for it.
The generic skills are a starting point. The ones that decide whether the factory is useful are the company-specific ones, which the playbook calls "custom ownership routing": how your company decides who owns a service, which tracker and which project an issue goes to, what evidence a team needs before it will accept a finding, and what your severity policy says. Nobody outside your company can write those for you without first sitting with the people who triage today, which is why the plan has investigators and skill authors working together for all six weeks, refining skills from investigation feedback.
The skill format is plain text and scripts, so the same ideas work with OpenAI's Codex, Anthropic's Claude Code or another agent framework. Pick the model by testing it on your own findings, the same way you would evaluate any other agent.
The six-week plan
The playbook proposes five workstreams over six weeks. Leadership mobilizes the team in week one and then runs a weekly review to make decisions and clear blockers. Security and application engineers fix urgent exposures from day one, investigating, patching, deploying and verifying. Application and platform teams link systems, code and owners in the first weeks and keep that inventory current. Platform and application teams make priority services run reproducibly, then extend. Investigators and skill authors codify what they learn into skills throughout.
It also asks leadership for three things: pause lower-priority work to free people, fund a focused surge (models, environments and approved access), and name an executive sponsor and a delivery lead who must show evidence that fixes work. That last request is the one that tends to be dropped, and it is what keeps the programme from turning into a dashboard nobody acts on.
How to know it works
The playbook suggests five measures for the first workflow, and we would use them as written. Coverage and readiness: where agents can test your systems and where access or setup leaves gaps. Finding quality: whether validation removes noise, so engineers trust what reaches them. Ownership and handoffs: where findings stall before reaching someone who can fix them. Verified remediation: whether deployed fixes close exposures faster without breaking services. Human effort and cost: whether the factory scales without a matching growth in people and spend.
The appendix lists published examples from February to August 2026, including Cloudflare running persistent discovery and validation across 128 repositories, and Ramp, where agents found, validated and patched about 100 issues in six days with humans reviewing the pull requests.
Where to start
If you are reading the playbook and deciding whether to act, we would start smaller than six weeks. Choose one source of findings you already have, such as dependency alerts or a static analysis tool. Choose three services that matter and can be made to run in a container. Build the loop for that slice from discovery to verified fix, with isolation and logging from the first day, and measure it. When the slice works, the inventory, the environments and the skills you built for it are the foundation for every other service.
That first slice is what we build for clients: one week to assess readiness and plan, then six weeks to put one workflow into production on your own tools. Our page on building a Defense Factory describes the engagement. If you want to talk it through, book a call.
Sources
The definition, the five stages, the architecture, the six-week workstreams, the skill names, the five measures, the Cloudflare and Ramp examples and the description of the Hugging Face incident are from OpenAI's Defense Factory playbook and its launch page. The 250-person sprint and the 53 issues closed on the first day are from RuntimeWire, September 9, 2026. The open letter and its signatories: Implicator. Daybreak: OpenAI Help Center.
Vindler Solutions is a member of the OpenAI Partner Network; this post is our own reading and is not endorsed by OpenAI. "Defense Factory" is the term used in OpenAI's playbook, which is the source for the definitions, stages, skills and measures quoted above.